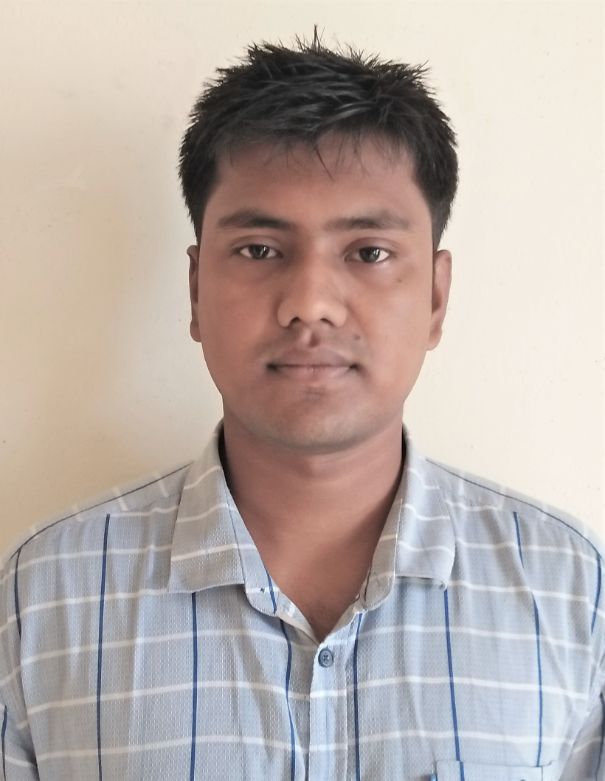
Md Romyull Islam
PhD Candidate in Computer Science
Kennesaw State University, GA, USA
PhD candidate in Computer Science at Kennesaw State University, working on language model optimization and edge computing. Previously: MS at Austin Peay State University, BS at Daffodil International University.
My research focuses on running large language models efficiently on edge devices; quantization, sparsity, and hardware-aware adaptation. I have published multiple peer-reviewed papers and actively contribute to the research community through conferences and collaborative projects.
Research Interests & Ongoing Work
Energy- and Thermal-Aware On-Device KV Management
On phones, language models are limited by memory, battery, and heat rather than by compute. My dissertation builds KV-cache management that keeps sustained inference fast within those limits. My system μKV decodes 4.8 times faster with 62% less energy on a Snapdragon phone.
Memory-Tiered LLM Inference on CXL
CXL devices that pair DRAM with flash give language models far more memory, but capacity, bandwidth, and endurance trade off. I study where weights, KV cache, and prefetched data should live across these tiers. My scheduler, SemSched, outperforms four published offloading policies.
Quantized Fine-Tuning and Sparse Inference
My method AQLoRA, decides in one data-free pass which layers keep higher precision during quantized LoRA fine-tuning, and it trains faster than tuned QLoRA without any search. With collaborators, I also study activation sparsity and storage-aware prefetching to reduce weight traffic during LLM inference.
Efficient Inference for AI Agents
AI agents call tools over many steps, and each step changes which context the model needs next. I study how agent workloads reuse the KV cache and design memory policies that understand the role of each token.
Characterizing Language Models on Edge Hardware
Good optimization starts with careful measurement. I measure the latency, energy, and memory use of small language models on Jetson Orin, Raspberry Pi, and mobile devices to find where the real bottlenecks lie.
Publications
MM-JEPA-TC: Low-Cost Multimodal Joint-Embedding Predictive Architecture for Tropical Cyclone Forecasting
Efficient Vision Knowledge Pipeline Systems on Resource-Constrained Edge Devices
Characterizing and Understanding Energy Footprint and Efficiency of Small Language Model on Edges
A Sparsity Predicting Approach for Large Language Models via Activation Pattern Clustering
Characterizing and Understanding the Performance of Small Language Models on Edge Devices
Activation Sparsity Opportunities for Compressing General Large Language Models
Building a Resilient and Sustainable Grid: A Study of Challenges and Opportunities in AI for Smart Virtual Power Plants
A Systematic Investigation of Hardware and Software in Electric Vehicular Platform
Living on the Electric Vehicle and Cloud Era: A Study of Cyber Vulnerabilities, Potential Impacts, and Possible Strategies
Machine Learning Techniques Applied to Predict Tropospheric Ozone in a Semi-Arid Climate Region
Volatility estimation for COVID-19 daily rates using Kalman filtering technique
Mobilenet model for classifying local birds of bangladesh from image content using convolutional neural network
A convolution neural network based classification approach for recognizing traditional foods of bangladesh from food images
Awards
News
Professional Experience
Technical Skills
Global Visitors
Loading…